General-Purpose AI vs Specialised Bid Tools: What the Evidence Shows in 2026
General AI assistants are now embedded in most bid teams. But is a generic model actually the right tool for bid writing? A look at the evidence on accuracy, memory, and feedback, without the vendor spin.
mytender.io Research Team
Tender Writing & Bid Management Specialists
General-Purpose AI vs Specialised Bid Tools: What the Evidence Shows in 2026
Almost every bid team now has access to a general-purpose AI assistant. According to Microsoft's website as of October 2026, Copilot Chat is available at no additional cost with an eligible Microsoft 365 subscription, and other general assistants are a browser tab away. So the reasonable question isn't "should we use AI for bids?" Most teams already are. It's "is a generic model actually the right tool for this particular job?"
For a side by side look at specialist tools, see our guide to the best AI bid writing software and our comparisons of mytender.io with Loopio and Bidwell.
That's a fair question to interrogate honestly, because the easy answer ("we already have Copilot, so we're covered") is cheap to justify internally and rarely tested. This piece looks at what the evidence says about where general models perform well, where they degrade, and what actually differs when a tool is built specifically for bid and tender writing.
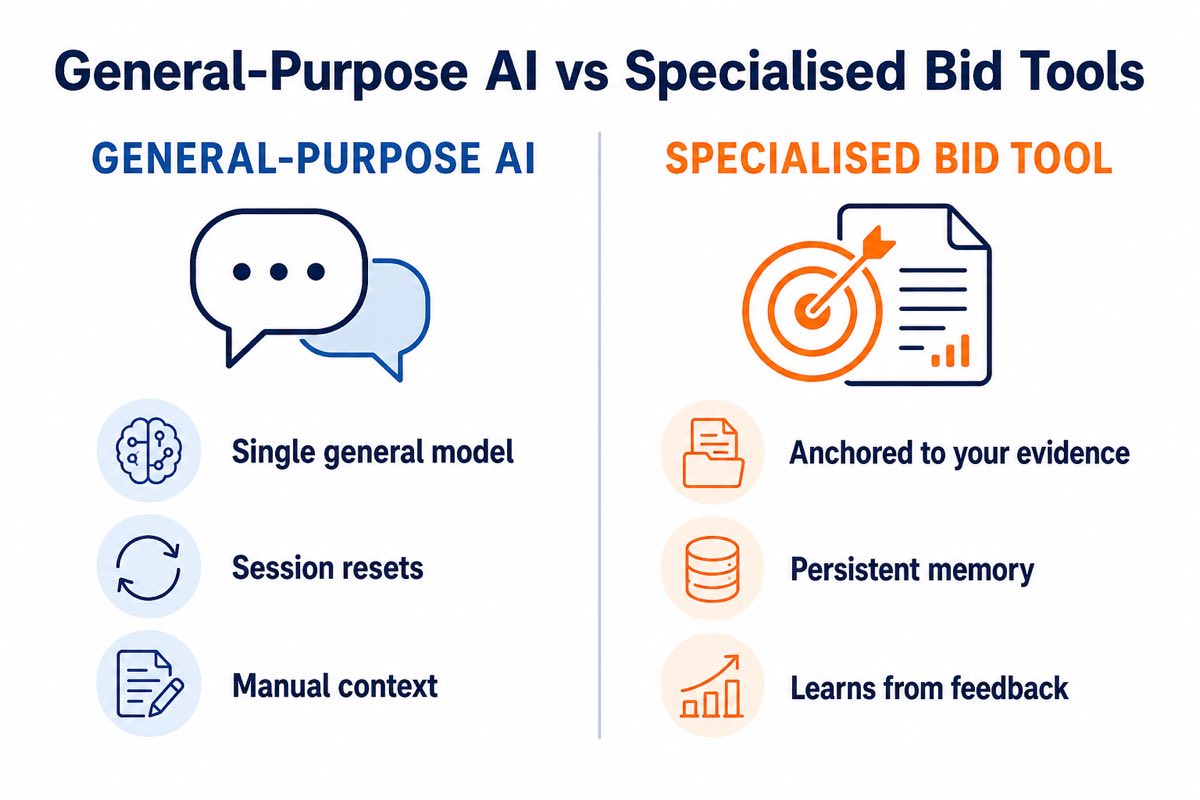
Comparison of general-purpose AI and specialised bid tools across accuracy, memory, workflow and feedback
First, Where General AI Genuinely Works
It's worth being clear-eyed. General-purpose models are useful, and dismissing them wholesale would be dishonest.
For summarising a long document, rewording a clunky paragraph, drafting a first pass at a standard question, or checking tone, they're fast and competent. Several bid teams report cutting drafting time on routine, repeatable questions substantially once they started using a general assistant. For the "we've answered this fifty times" category of question, such as standard quality management statements or generic health and safety narratives, a general model gets you a serviceable draft in minutes.
The problem isn't that general AI is bad. It's that bid writing is a specialised, high-stakes, compliance-heavy domain, and that is precisely the kind of task where general models behave differently from how they behave on everyday writing.
The rest of this article looks at four structural gaps, and what the external research says about each: accuracy in complex domains, memory, workflow, and learning from feedback.
Gap 1: Accuracy Degrades in Complex Domains
Every large language model fabricates information some of the time. What matters for bid writing is how often, and where.
Independent research gives a sense of the scale. AuthenHallu, a benchmark built from 800 real exchanges between users and 25 different models and published at LREC 2026, found hallucinations in 31.4% of responses, rising to 60% for the hardest topics it measured: maths and number problems, and dates and calendar questions (Detecting Hallucinations in Authentic LLM-Human Interactions). Bid writing was not one of the topics tested, so those figures are not a measure of bid accuracy. What they do show is that error rates are not uniform, and that they climb on precise, figure-heavy detail.
Bid writing involves a lot of that kind of detail: technical specifications, compliance-specific language, client history, project figures and dates, and evidence that has to be accurate to survive evaluation.
There's a compounding risk on top of the raw error rate. A 2025 University of California San Diego study found that the models it tested hallucinated on 60% of fact-checking questions about news published after their training data, and that people who read a positively reframed AI summary of a product review were 32% more likely to choose that product than people who read the original review (Alessa et al., IJCNLP-AACL 2025). AI-written text changed what readers decided, even where it had shifted the meaning of its source. Fluent, confident writing reads as credible whether or not it's true. In a bid context, that's how a fabricated statistic or an overstated capability slips into a submission that a human then signs off because it "reads well."
The failure mode bid teams describe most is a model quietly "improving" details it shouldn't touch, such as inflating a qualification, embellishing a project figure, or adding a claim. It does this because it is optimising for how the text reads, not for whether it's true. Asked why, these models will often justify it in exactly those terms: it reads better. In most writing, that instinct is helpful. In a tender, where an evaluator can check a CV or a certification, it's a liability.
The practical takeaway isn't "don't use AI." It's that in a complex domain, accuracy depends heavily on the model being anchored to real, structured, verified source material, and a general model used from a blank chat window has none of that anchoring by default.
Gap 2: Memory That Evaporates
This is the clearest structural difference, and it's easy to miss because it isn't a feature you can see failing.
With a general assistant, the context window closes after every prompt. Each bid is effectively a fresh session. None of the nuance you explained last week carries forward: your preferred tone, the client's history, which case studies are approved, what an evaluator penalised you for last time. You re-teach a blank model every time.
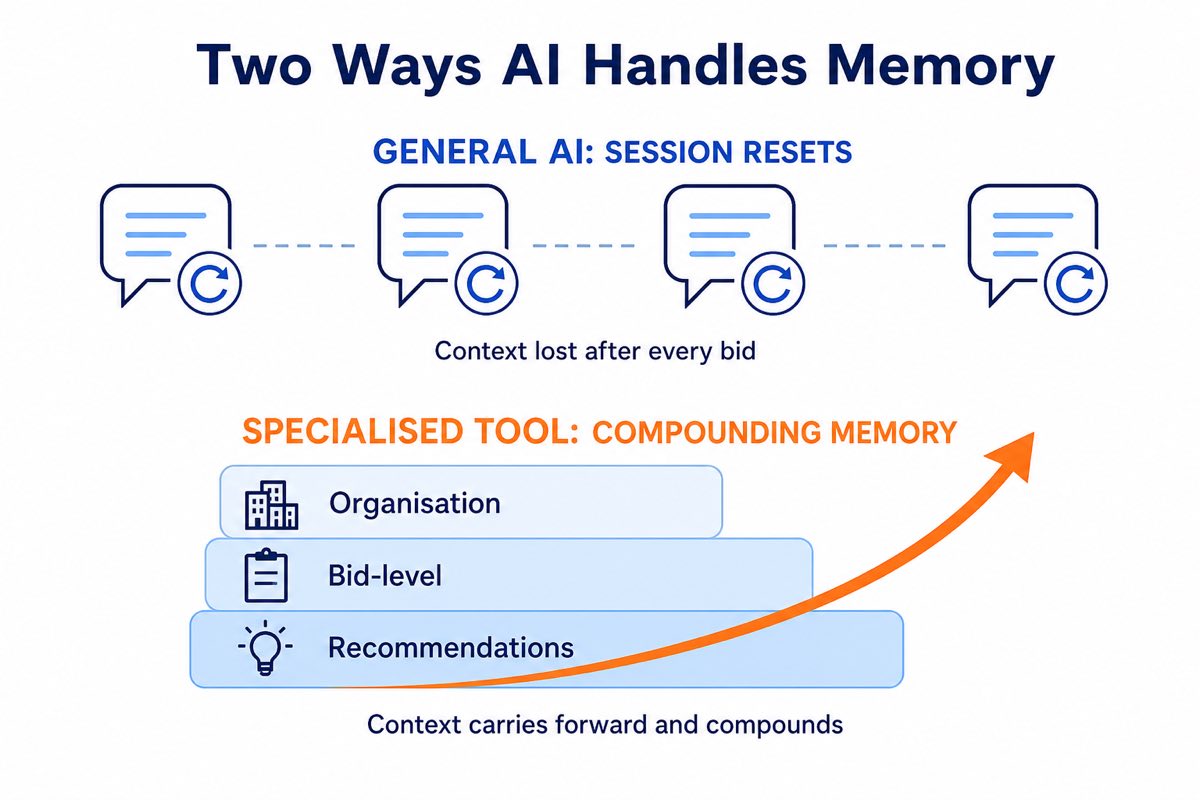
Session-based memory versus a compounding knowledge layer across bids
Put simply, a chat session's context disappears when the session ends, while a knowledge base built from past bids keeps growing. That distinction matters more over time than any single-draft comparison. A team using session-based AI is renting a capable but forgetful assistant. A team whose tooling retains organisational context, such as past bids, feedback, content-library patterns and per-bid detail, is building an asset that gets sharper with every submission.
This is where a specialised approach diverges structurally rather than cosmetically. A purpose-built bid tool can hold a persistent memory across three layers: an organisational layer (patterns and feedback from past bids, the content library), a bid-level layer (the context for the specific tender in front of you), and self-updating recommendations that improve over time. A general chat interface, by design, resets. You can paste context back in, but you're doing the remembering; the tool isn't.
Gap 3: Instruction Drift
Related to memory, but distinct enough to call out: general models tend to drift.
A common, well-documented pattern is that you give a model clear instructions: use only this source material, don't touch these figures, follow this structure. It holds them for the first few tasks, then gradually reverts to its own defaults after four or five prompts. For casual writing, that's a minor annoyance. For bid writing, where you may be working strictly from a gold-standard answer bank or a fixed evidence set, drift is a quality and compliance risk. You end up re-issuing the same instructions and re-checking the same outputs, which erodes the time saving that made the tool attractive in the first place.
Stability under constraint, reliably working from only the approved information, is a specific requirement of bid writing that general models are not optimised for.
Gap 4: The Team Becomes the Integration Layer
Even where a general assistant drafts well, it drafts in isolation. It doesn't hold your content library, track review status, manage versions, or route work to reviewers. All of that still happens by hand.
The result is fragmentation that bid managers describe consistently: lots of separate chats, copy-pasting outputs between tools, stitching together drafts, reviewer comments, version control and status tracking manually. The more bids a team runs through a general assistant, the messier this gets over time. Bolting "agents" onto a chat interface doesn't remove the stitching; someone still sets them up and moves work between them.
That's real cognitive load. It never appears on a slide, but it shows up in every late night before a submission deadline. The value of a single system isn't a longer feature list; it's that the team's mental energy goes into winning the bid rather than managing the process around it: one place to draft, remember, review and track, instead of six open tabs reconciled by a human.
Gap 4b: Learning From Wins and Losses
If there's one thing general AI structurally cannot do for a bid team, it's turn a lost bid into a better next bid automatically.
When an evaluator says a response was too generic, missed a requirement, or scored poorly, that feedback is the most valuable intelligence a bid team ever receives. With a general assistant, that learning has to be captured and reapplied entirely by people: someone has to save the feedback, decide it's relevant next time, find the original question and answer it related to, re-supply that context, and remember to do it again for every future bid. Most teams don't do this consistently. The learning stays trapped in individuals and folders.
"Can't I just upload the feedback to the AI?" You can, but uploading a note isn't the same as having the learning applied. A general model will only use what somebody remembers to find and give it that day. It won't reliably know which past feedback is relevant, what answer it relates to, or why that answer lost marks.
A tool built for bids can keep the feedback connected to the original question, source material and answer, then apply the lesson automatically when a similar question comes up. In bid-writer terms, that means:
- Less rework: fewer repeated mistakes, and fewer senior reviews correcting the same issue twice.
- Better continuity: a new bid writer inherits the lessons learned by whoever wrote the last bid.
- A library that maintains itself: every answer, evaluator comment and final edit becomes usable knowledge, not admin someone has to curate.
- Compounding quality: the more bids the team writes, the more relevant evidence there is to draw on, rather than more documents to search through.
A general assistant gives you a place to store lessons. A specialised system turns every bid and every piece of feedback into something the whole team actually uses next time.
What a Like-for-Like Test Showed
Comparisons like this can stay abstract, so it's worth grounding at least one in data, with the caveats stated plainly.
In an internal test across 14 questions drawn from three live public-sector tenders, responses from a purpose-built bid tool (mytender) were scored against each tender's own published quality criteria alongside responses from a general-purpose model used without bid-specific context. The bid tool scored 52.5% against those criteria versus 38.9% for the general model, a gap of 13.6 percentage points.
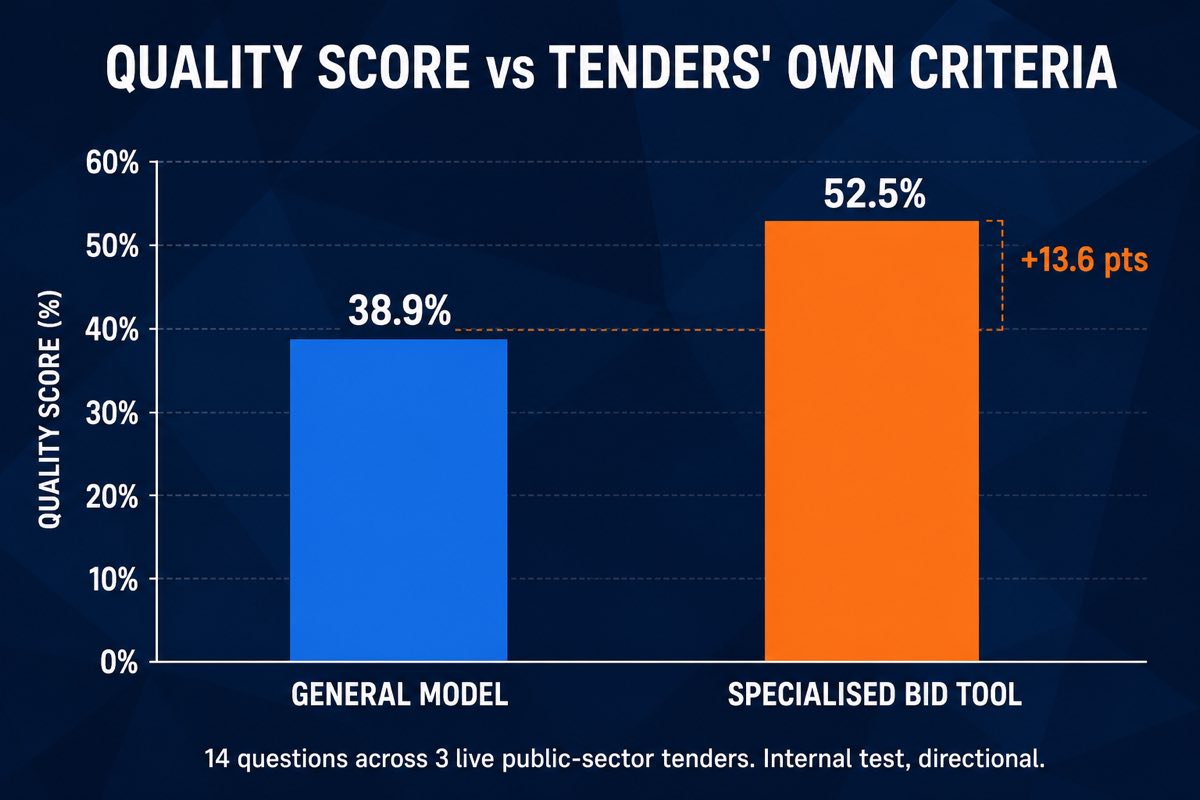
Benchmark comparison: specialised bid tool versus general model against tenders' own quality criteria
Two honest caveats. First, the sample is small and the test was run internally, so treat it as directional rather than definitive. Second, the measured advantage was specifically in relevance to the specification and completeness of response: the specialised tool produced answers that were more tightly matched to what each tender actually asked for, and left fewer requirements unaddressed. It is not a verified claim about raw factual accuracy.
That distinction is telling in itself. The difference didn't come from the general model being incapable of good prose; it's from the specialised tool being anchored to the specification and the relevant evidence, which is the "complex domain" and "memory" points from earlier showing up in an actual result.
Compliance and the AI-Detection Shift
Two developments make the tool choice a governance question, not just a quality one.
First, informal AI use creates a paper trail. Where an approved assistant does not meet a team's needs, individuals sometimes reach for personal AI subscriptions instead, a workaround that can create compliance risk detectable in document metadata. For teams in defence, government or other regulated sectors, where data resides and how it's processed is a real procurement consideration, and a UK-based security posture is a meaningful differentiator.
Second, the market is changing on the buyer side. Clients increasingly ask bidders to declare their use of AI, and experienced evaluators report being able to spot generic, AI-generated content. A polished but obviously templated response is now a risk in itself. That raises the bar from "can AI produce a draft?" to "can AI produce a response specific enough to the client and specification that it doesn't read as generic?" That loops back to relevance and context, the areas where general models are weakest.
The Wider Trend: Specialised Over Generic
There are signs of the same shift outside bid writing, at least in one heavily regulated sector. Menlo Ventures' 2025 State of AI in Healthcare report, based on a Morning Consult survey of more than 700 US healthcare executives, found that 22% of US healthcare organisations had implemented domain-specific AI tools, around 7x the 2024 rate and 10x the 2023 rate (Menlo Ventures, October 2025). That is one sector and one survey, not a measure of bid teams, but it shows organisations doing compliance-heavy work choosing purpose-built tools.
There's a strategic warning attached, too. In February 2025 Gartner predicted that through 2026, organisations will abandon 60% of AI projects unsupported by AI-ready data (Gartner press release, 26 February 2025). That's directly relevant to any team weighing whether to build its own internal AI layer on top of a general model: without the data foundation, the effort tends to stall. The durable advantage isn't the base model, which is broadly available to everyone, including your competitors; it's the proprietary, compounding context that a specialised system accumulates and a generic chat window discards.
The Bottom Line
This isn't an argument that general-purpose AI is useless, or that the two approaches are mutually exclusive. General assistants work broadly and will keep earning their place for everyday tasks.
The point is narrower and better supported by evidence: bid writing is a complex, compliance-heavy, memory-dependent domain, and that is exactly where general models are weakest. They make more errors on precise, detail-heavy material, forget context between sessions, drift from instructions, leave the team as the integration layer, and can't turn feedback into future performance on their own. A tool built specifically for bids addresses those gaps by design rather than by asking a person to compensate for them.
If you already lean on a general assistant, the useful exercise isn't to rip it out; it's to notice where it's costing you: the re-explaining, the copy-pasting between chats, the near-misses where a figure got "improved," the feedback that never made it into the next bid. Those are the seams where a specialised approach pays for itself.
mytender.io is built specifically for bid teams: anchoring drafts to your own content and evidence, retaining context across bids, and turning evaluator feedback into a lesson the whole team reuses.If you'd like to see live opportunities matched to your sector while you weigh up your tooling, the Tender Finder is free to use and updated daily.
---
About this article: statements about named products are based on each company's own public website as of 16 October 2026 and may have changed since. External research is linked to its original source, checked on 20 October 2026. The benchmark above is mytender's own internal test and is not a claim about any named product. Product names are trademarks of their owners. If you believe anything here is inaccurate or out of date, please email info@mytender.io or contact us and we will review and correct it promptly.Tags
Ready to Transform Your Tender Writing?
See how MyTender's AI can help you write winning tenders in a fraction of the time.